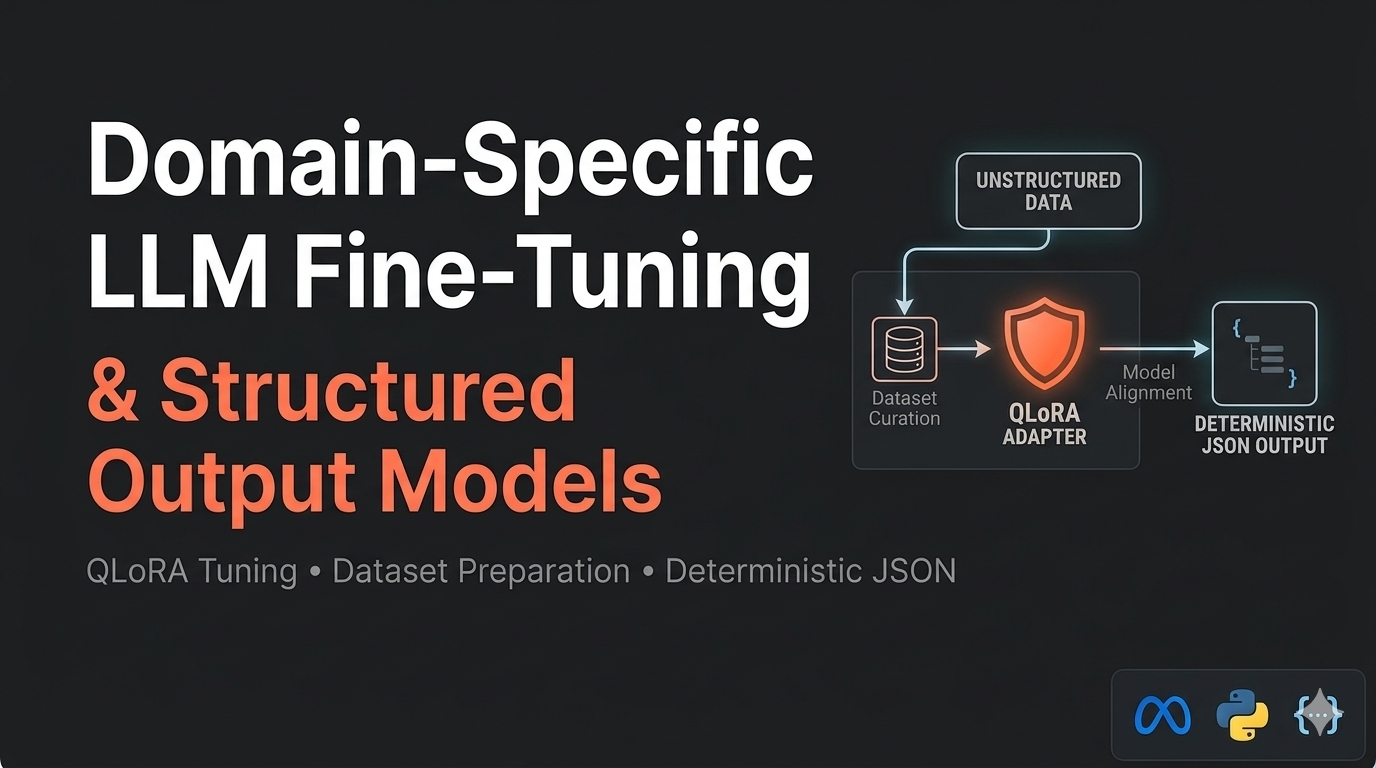
I will fine-tune open-weight LLMs with QLoRA for domain-specific tasks and deterministic JSON outputs.
Add Extra Services
About this Gig
Stop burning cloud budget on long, complex zero-shot prompts that fail to return reliable data. I fine-tune domain-specific open-weight models (like Llama 3 and Mistral) to deliver highly specialized, deterministic, and structurally perfect responses at a fraction of standard API call costs. If your current system requires strict JSON schemas, domain-specific terminology (legal, medical, financial), or low-latency classification logic that generic models consistently fail to hit, a specialized parameter-efficient adapter is the definitive production solution. What this service includes: - Custom Dataset Curation: Clean data parsing, orchestration, and preparation of instruction-tuning pairs tailored to your exact domain logic. - Parameter-Efficient Fine-Tuning (PEFT): Implementation of production-grade QLoRA methodologies to drastically minimize cloud compute footprint while maximizing fine-tuning accuracy. - Strict Schema & Structured Outputs: Training models to hit complex, deterministic JSON object configurations reliably for seamless programmatic parsing. - Multi-LLM Alignment & Calibration: Hardening target models against failure modes using system constraints and specialized function-calling guardrails. - Deployed API Infrastructure: Packaging fine-tuned adapters inside clean FastAPI wrappers or containerized inference servers ready for active workloads.
Requirements
To efficiently scope the fine-tuning training lifecycle, please provide: 1. A sample or repository of the raw source data you want the model to learn from (e.g., historical documents, text logs, existing input-output examples). 2. The target output formatting rule or exact JSON schema you need the model to match every time. 3. Your core computational budget target or preferred cloud ecosystem (e.g., RunPod, Modal, AWS, GCP).
